bang for buck, not bang for ego
Coding models ranked by dollars per solved task.
Measured cost per solved task in the waterfall.sh harness. Not list price. Not vendor SWE-bench.
How to read this
Value is quality per dollar spent on a solved task, normalized so the board leader is 100.
The quality ceiling is useful, but it is not the same thing as the best default.
Snapshot costs are public priors; harness costs include retries and failed attempts as measured runs replace them.
Cache reads can change Fable economics, so Waterfall will not recommend Fable on cost unless the harness actually cached the stable prefix.
| Rank | Model | List in / out | Cache read | Cost / attempt | Best for | Updated | ||||
|---|---|---|---|---|---|---|---|---|---|---|
| 1 | DeepSeek V4 Flashmedium · snapshot | 72 | $0.22 / $0.66 | none | $0.19 | pending | 62% | 100.0 | High-volume first pass | 2026-09-03 |
| 2 | MiniMax M3medium · snapshot | 74 | $0.30 / $1.20 | none | $0.35 | pending | 70% | 55.8 | Cheap capable implement | 2026-09-03 |
| 3 | GLM-5.3max · snapshot | 86 | $1.40 / $4.40 | none | $0.68 | pending | 78% | 33.4 | Frontier-cluster value | 2026-09-03 |
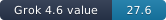
| 4 | Grok 4.6medium · snapshot | 88 | $2.00 / $6.00 | none | $0.84 | pending | 80% | 27.6 | Default implementer | 2026-09-03 |
| 5 | Kimi K3max · snapshot | 87 | $3.00 / $15.00 | none | $0.94 | pending | 82% | 24.4 | Frontend / UI agents | 2026-09-03 |
| 6 | Claude Opus 5high · snapshot | 93 | $5.00 / $25.00 | none | $2.34 | pending | 90% | 10.5 | Quality floor / review | 2026-09-03 |
| 7 | Claude Fable 5.1high · snapshot | 96 | $10.00 / $50.00 | $0.25 | $2.72 | pending | 93% | 9.3 | Escalate after Opus fails | 2026-09-03 |
| 8 | Claude Fable 5.1max · snapshot | 98 | $10.00 / $50.00 | $0.25 | $3.76 | pending | 95% | 6.9 | Ceiling only | 2026-09-03 |
| 9 | GPT-5.6 Terramax · snapshot | 89 | $2.00 / $12.00 | none | $4.95 | pending | 84% | 4.7 | OpenAI everyday agent | 2026-09-03 |
| 10 | GPT-5.6 Solmax · snapshot | 92 | $4.00 / $20.00 | none | $8.39 | pending | 89% | 2.9 | Tool-heavy agents | 2026-09-03 |
Coverage: borrowed scores, not measured
Loading catalog coverage.
Everything above has a measured or dated cost per solved task. Everything below does not. These rows borrow Artificial Analysis coding_index (or intelligence_index, or rescaled Design Arena Elo) from OpenRouter's catalog so the other two hundred models are at least visible. No value score, because the formula needs a measured cost per solved task. Prices are list, per 1M tokens.
| # | Model | Borrowed quality | Source | List in / out | Context | Efforts |
|---|---|---|---|---|---|---|
| Coverage needs the JSON feed; see /api/leaderboard.json. | ||||||
Waterfall default stack
Cheap first. Independent review. Expensive only after a blocking failure.
Methodology
Score
value_raw = quality / max(cost_per_solved, 0.01)
value = 100 × value_raw / max(value_raw on board)
Harness quality is the equal-weight mean of pass rates across task categories. A solve means the declared tests or blocking reviewer gate passed on the first submitted attempt.
Source and sample
snapshot-2026-09-03 means a prior compiled from public September 2026 reporting and list prices. It is not a Waterfall measurement, so cost per attempt and n remain pending.
harness means committed task-level records from data/runs/*.jsonl, including model, effort, tokens, cache reads, cost, wall time, pass/fail, promotions, and reviewer verdict.
Context, not borrowed results
SWE-bench, Artificial Analysis, and DeepSWE are useful external context. Their scores are never relabeled as Waterfall harness numbers.
The shipped suite is intentionally small: 5 one-file bugfixes, 5 multi-file features, 3 review-only diffs, and 2 long-horizon finish-the-PR tasks.
coverage rows are the exception that proves the rule: borrowed AA and Design Arena scores pulled from OpenRouter's catalog for models the harness has not run, kept in their own table with their own field names so they cannot be mistaken for measurements.
Snapshot date: 2026-09-03. Prices move; this row is dated. Rebuild the feeds with waterfall leaderboard --publish.